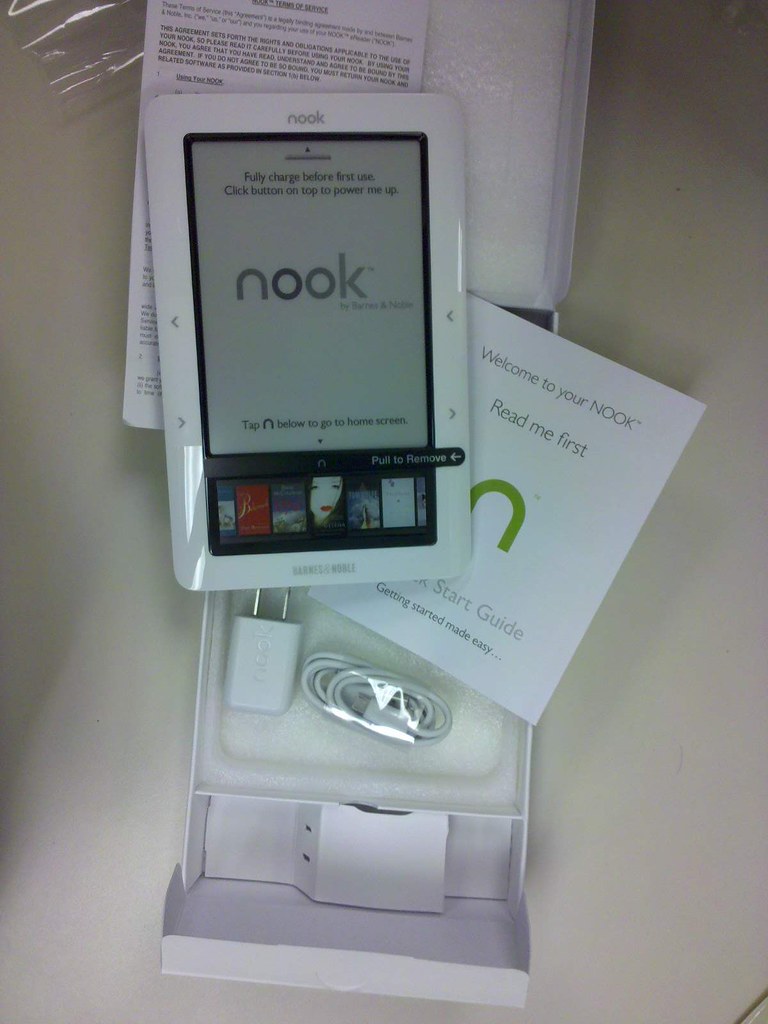
Finally, after more than two weeks' waiting, my nook was delivered to me.
nook and accessories:
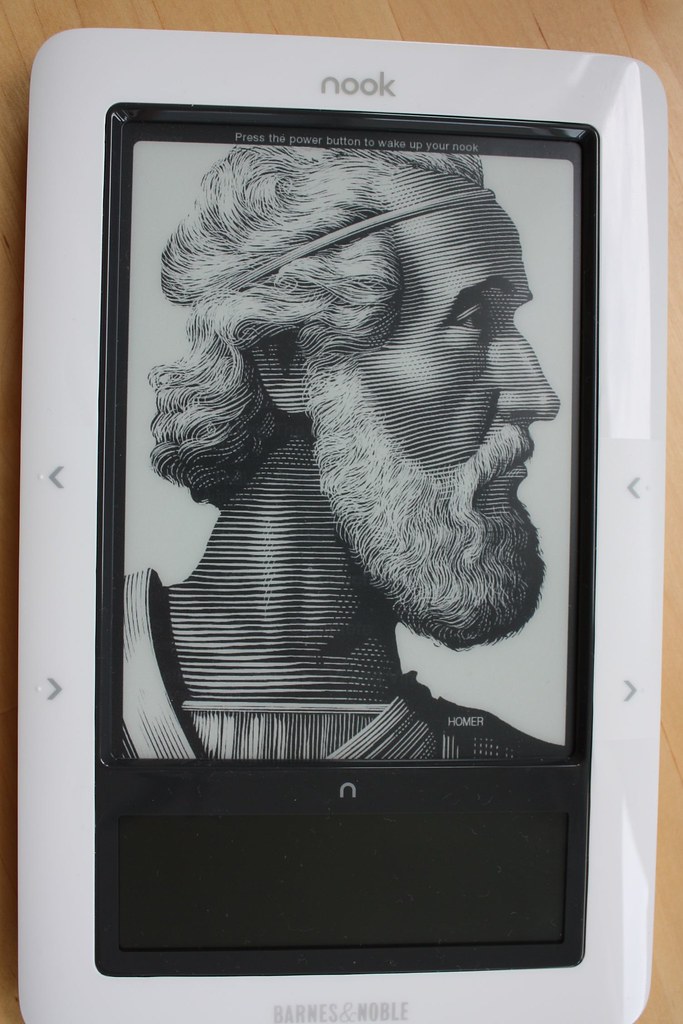
screensaver:
main menu:
viewing pdf:
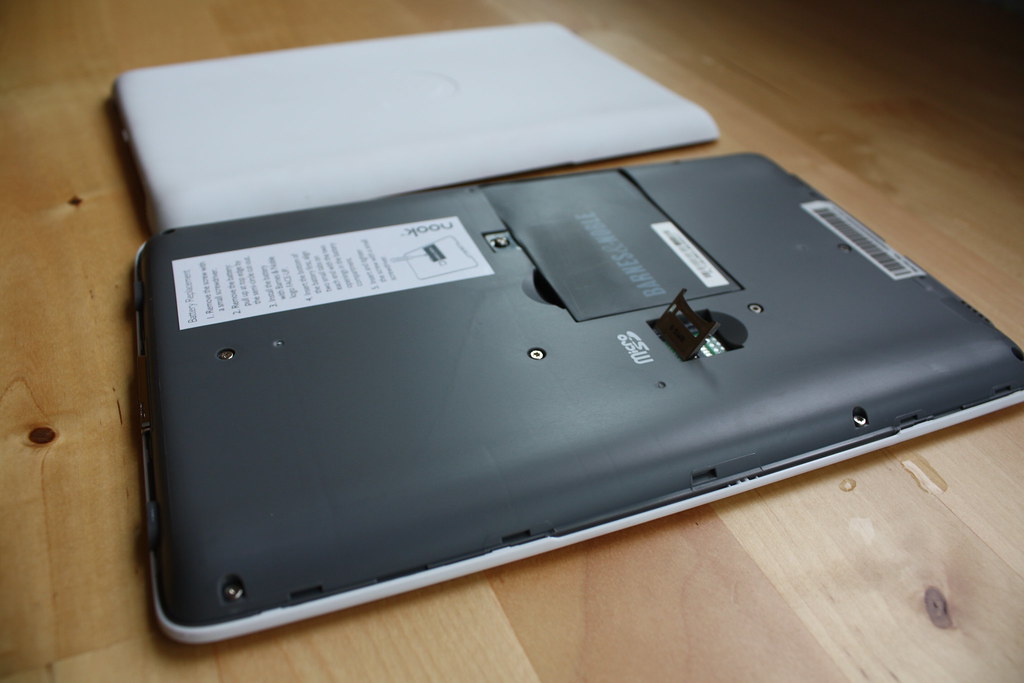
micro-sd card socket:
There are two set of go to previous/next buttons on both left and right side of nook for user's convenience. But they are rather hard to press, and make tick noise upon pressing. A bit annoying if use it in a quiet environment. Then I found in nook's manual that the touch screen in the bottom can also be used for navigation. After the touch screen goes dark, I can swipe my finger on it to navigate. A quick (must be quick enough) swipe from right to left turns to next page, and the oppisite direction turns to previous page. No noise at all.
A flaw with this clever design is the direction of swiping on touch screen is different from the hard button's arrow direction. The hard previous button has a left arrow on it. But the direction for turnning to previous page is from left to right. So wierd.
Saturday, July 17, 2010
Wednesday, July 7, 2010
performance impact of printf
Logging is a widely used debugging means. As a way of implementing logging, I saw printf used in a lot of places. It's so quick and easy to use printf to examine the behavior of an application. But it also has heavy impact of the performance of the application, meanwhile, it makes our logging a mess and difficult to read without careful forethought.
The code snippet below calculates the fibonacci number. On line eight, I used printf to print some values. Very simple code. I compiled the code with different printf statement on line eight and run the application to see the performance.
The list below shows the time ticks spent with different printf statements, in decreasing order.
It's very clear that the performance drops dramatically if the printf statement is there, and the more complex the format string is, the poorer the performance is. The performance is even 2000 times poorer if we compare the worst case and best case.
The reason is printf needs to invoke system call to output data, which incur a lot of transitions between user mode and kernel mode. And a complex format string also consumes a lot of processing time.
In order to get rid of the performance penalty, yet keep the capability of saving log. We must use a mature logging system, instead of printf directly. An ideal logging system should support switch, logging level and many output mechanisms.
While writing code, we're always enticed to use printf simply because it's easy to write. In contrast, a logging system should require us spending 10 minutes to understand and use. But, the time spent really deserves, considering the time we must spend later on organizing and cleaning printf statement and the possible performance impact of printf.
The code snippet below calculates the fibonacci number. On line eight, I used printf to print some values. Very simple code. I compiled the code with different printf statement on line eight and run the application to see the performance.
1 int fib(int a)
2 {
3 int rc = 0;
4 if(a < 2)
5 rc = a;
6 else
7 rc = fib(a-1) + fib(a-2);
8 printf("rc = %d, a = %d\n", rc, a);
9 return rc;
10 }
11
12 int main(int argc, char* argv[])
13 {
14 int t1 = GetTickCount();
15 printf("before fib: %d\n", t1);
16 int result = fib(16);
17
18 int t2 = GetTickCount();
19 printf("after fib: %d %d %d \n", t2, t2 - t1, result);
20 return 0;
21 }
22
The list below shows the time ticks spent with different printf statements, in decreasing order.
4188 (printf("rc = %d, a = %d\n", rc, a) )
3617 (printf("helloworld"))
844 (printf("a"))
858 (printf("%d\n", rc))
302 (printf("%d", rc))
2 (no printf)
3617 (printf("helloworld"))
844 (printf("a"))
858 (printf("%d\n", rc))
302 (printf("%d", rc))
2 (no printf)
It's very clear that the performance drops dramatically if the printf statement is there, and the more complex the format string is, the poorer the performance is. The performance is even 2000 times poorer if we compare the worst case and best case.
The reason is printf needs to invoke system call to output data, which incur a lot of transitions between user mode and kernel mode. And a complex format string also consumes a lot of processing time.
In order to get rid of the performance penalty, yet keep the capability of saving log. We must use a mature logging system, instead of printf directly. An ideal logging system should support switch, logging level and many output mechanisms.
While writing code, we're always enticed to use printf simply because it's easy to write. In contrast, a logging system should require us spending 10 minutes to understand and use. But, the time spent really deserves, considering the time we must spend later on organizing and cleaning printf statement and the possible performance impact of printf.
Labels:
c++,
performance
Monday, July 5, 2010
paste in vim command line
To be able to paste something to vim's command line is a feature makes our life a lot easier. For instance, say we want to change a frequently used variable name in c source file from a_super_long_inproper_variable_for_caching_bank_account_balance to balance. To replace all of the variable's occurrence, we plan to use following replace command:
Luckily, vim has at least two ways to rescue us from having to type the name.
1. command-line window
command-line window is a separate window that enables us editing command just like working in a normal window. Plus, it lists command history. So, we can easily copy the variable name via yank command and paste it to command-line window. To open the command-line window, we can type q: while in normal mode. For more information about command-line window, see help q: in vim.
2. paste with Ctrl+R shortcut key combination
Instead of opening a separate command-line window, we can also paste directly in vim command line. While editing within command line, we can use Ctrl+R, Ctrl+W key combination to paste the word currently under cursor in last window to command line. Beside the forgoing shortcut key, vim features a lot of key combination that let us paste from different sources, like registers, file name, etc. Run :help c_CTRL-R to find more out its real power.
Reference:
Vim documentation: cmdline
:%s/a_super_long_inproper_variable_for_caching_bank_account_balance/balance/g
Without paste capability, we have to type the variable name ourself, maybe several times because we doom to type the name wrong.Luckily, vim has at least two ways to rescue us from having to type the name.
1. command-line window
command-line window is a separate window that enables us editing command just like working in a normal window. Plus, it lists command history. So, we can easily copy the variable name via yank command and paste it to command-line window. To open the command-line window, we can type q: while in normal mode. For more information about command-line window, see help q: in vim.
2. paste with Ctrl+R shortcut key combination
Instead of opening a separate command-line window, we can also paste directly in vim command line. While editing within command line, we can use Ctrl+R, Ctrl+W key combination to paste the word currently under cursor in last window to command line. Beside the forgoing shortcut key, vim features a lot of key combination that let us paste from different sources, like registers, file name, etc. Run :help c_CTRL-R to find more out its real power.
Reference:
Vim documentation: cmdline
Labels:
productivity,
tools
Thursday, July 1, 2010
perform profiling on windows ce
Profiling is an effective way of finding out bottlenecks in an application. On windows ce platform, profiling can also be done easily.
To perform profiling for native code, we can use the /callcap compiler option to enable callcap profiling. After it's enabled, the compiler will inject method invocation to _CAP_Enter_Function and _CAP_Exit_Function upon entering and returnning from a function respectively. We can print or log current time in these method to achieve profiling.
It's notable that while compiling the source file contains _CAP_Enter_Function and _CAP_Exit_Function's definition, we must disable /callcap option, otherwise, these function will call themself recursively. In most cases, it's a wise idea to create a library project to implement these profiling hook fuction and trun /callcap off for the project. Then link the library to other applications to be profiled.
For demonstration, here is a visual studio project shows how to do profiling:
http://code.google.com/p/rxwen-blog-stuff/source/browse/trunk/wince/ce_profiling/
After we run the application, we get below output:
As you can see, it's a very rough sample that only prints the address of function being called. Not convenient to analyse. We may improve it by mapping and translating the address to function name, because we, as the application developer, possess the private symbol file. This task doesn't need to be done on the windows ce box, it's much easier to save the log file then parse and analyse it on a pc.
References:
Remote call profiler
A tour of windows ce performance tools
To perform profiling for native code, we can use the /callcap compiler option to enable callcap profiling. After it's enabled, the compiler will inject method invocation to _CAP_Enter_Function and _CAP_Exit_Function upon entering and returnning from a function respectively. We can print or log current time in these method to achieve profiling.
It's notable that while compiling the source file contains _CAP_Enter_Function and _CAP_Exit_Function's definition, we must disable /callcap option, otherwise, these function will call themself recursively. In most cases, it's a wise idea to create a library project to implement these profiling hook fuction and trun /callcap off for the project. Then link the library to other applications to be profiled.
For demonstration, here is a visual studio project shows how to do profiling:
http://code.google.com/p/rxwen-blog-stuff/source/browse/trunk/wince/ce_profiling/
After we run the application, we get below output:
Enter function (at address 00011068) at 73875892
Enter function (at address 00011030) at 73875897
Enter function (at address 00011000) at 73875902
bar
Leaving function (at address 00011000) at 73876907
foo
Leaving function (at address 00011030) at 73879912
Leaving function (at address 00011068) at 73879916
Enter function (at address 00011030) at 73875897
Enter function (at address 00011000) at 73875902
bar
Leaving function (at address 00011000) at 73876907
foo
Leaving function (at address 00011030) at 73879912
Leaving function (at address 00011068) at 73879916
As you can see, it's a very rough sample that only prints the address of function being called. Not convenient to analyse. We may improve it by mapping and translating the address to function name, because we, as the application developer, possess the private symbol file. This task doesn't need to be done on the windows ce box, it's much easier to save the log file then parse and analyse it on a pc.
References:
Remote call profiler
A tour of windows ce performance tools
Friday, June 25, 2010
openoffice exports better pdf than word
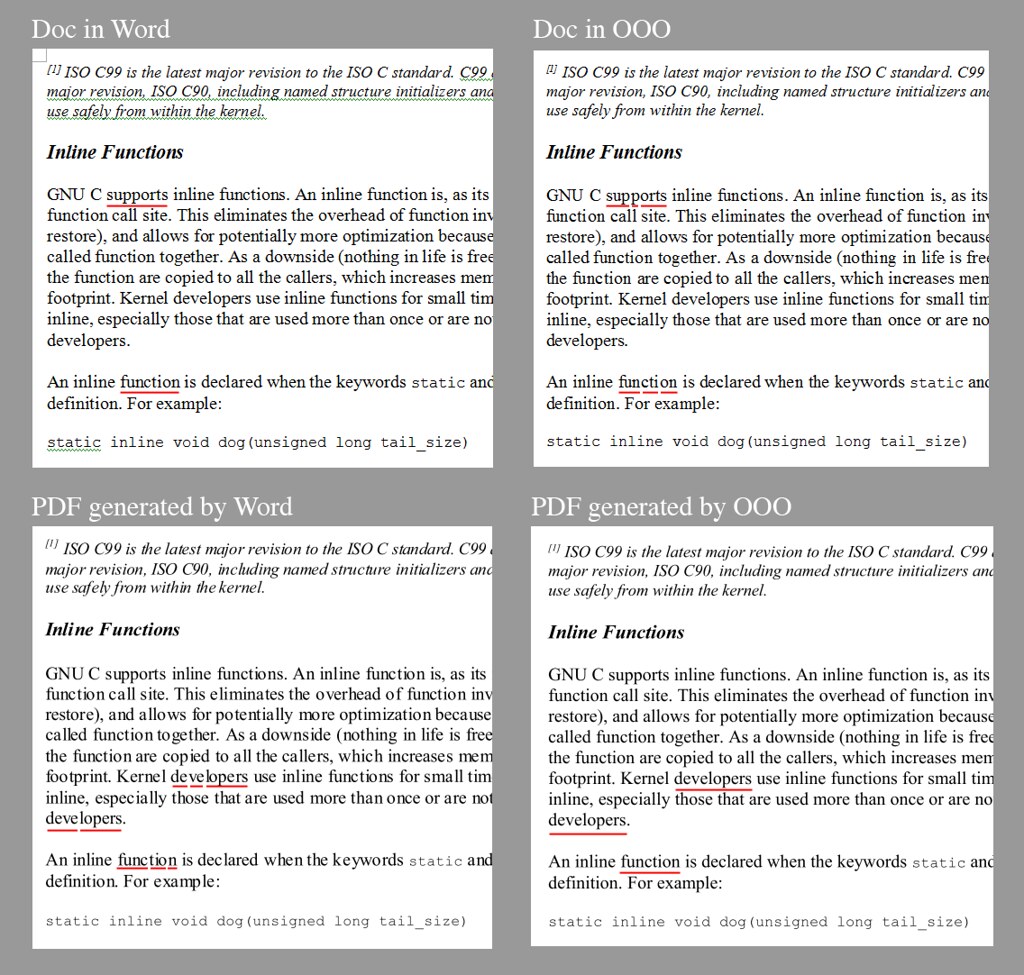
I generated a pdf file from a word document with word 2007. But the pdf file looks very uncomfortable in my pdf viewer. So I looked it closely to see what makes me feel so. The culprit is the spacing between characters. As shown in the image blow, the spacing between characters within a word varies in the pdf file, though the original word document doesn't exhibit this.
I tried to export the pdf file with openoffice again. To my surprise, the generated file looks very smooth and comfortable. The spacing between characters is perfect, just as they are in doc file. Also, the edge of the font is much more clear.
I usually don't pay much attention to details like fonts and spacing. But the performance between word and openoffice differs so much that it's hard to not to notice them. I just don't get how word deserves its price.
Labels:
tools
Wednesday, June 9, 2010
debugging python script in ipython
ipython doesn't work with built-in pdb debugger. While I tried to debug a python script with "run -d script.py" within ipython shell, I got bellow error:
To debug script in ipython, we need to use a different debugger, pydb, for example. There are only three steps to setup and use it.
Because pydb use the same set of commands with gdb, it's fairly straightforward to get start with it if you have done some debugging in gdb. This is one reason why I pick it as my debugger.
Reference:
Introducing the pydb Debugger
Debugging in Python
AttributeError: Pdb instance has no attribute 'curframe'
To debug script in ipython, we need to use a different debugger, pydb, for example. There are only three steps to setup and use it.
- download and install pydb.
- start ipython with -pydb argument: ipython -pydb
- start debugging with: run -d script.py
KeyError: 'HOME'
It can be solved by adding HOME environment variable.Because pydb use the same set of commands with gdb, it's fairly straightforward to get start with it if you have done some debugging in gdb. This is one reason why I pick it as my debugger.
Reference:
Introducing the pydb Debugger
Debugging in Python
Sunday, June 6, 2010
install ipython and readline on mac
ipython is a powerful interactive shell for python. With it, we can tak advantage of python programming language in our daily works.
One of ipython's power is its tab-completion feature that needs readline to work. On mac system, it lacks this library due to license issue. There is a proprietary version of readline in mac, but it doesn't work with ipython.
To install them on mac system, we can simply use easy_install utility, like this:
sudo easy_install ipython readline
Saturday, May 22, 2010
use ffmpeg to setup streaming server on android
ffmpeg is a powerful media library. It provides ffserver tool that can be used to setup a streaming server.
Here is how to compile ffmpeg for android, using CodeSourcery's cross compiler.
1. Download and extract ffmpeg source code.
2. Use below commands to compile ffmpeg
4. Transfer ffserver tool, ffserver.conf file (defines what media files will be served by ffserver) and media files to android with adb push command
5. Start streaming server with ./ffserver -f ffserver.conf on andoird shell
Below is a sample ffserver.conf file, which tells the ffserver to listen on rtsp port 7654. It defines two media files for streaming, /data/1.mp3 and /data/1.mp4, respectively. So make sure these files exist.
To test ffserver, we can start a media player that supports media streaming, and open the url: rtsp://{ip address of the android device}:7654/1.mp3.
Here is how to compile ffmpeg for android, using CodeSourcery's cross compiler.
1. Download and extract ffmpeg source code.
2. Use below commands to compile ffmpeg
./configure --arch=arm --cross-prefix=arm-none-linux-gnueabi- --extra-ldflags=-static --target-os=linux
make
3. Run file ffserver && readelf ffserver -d or arm-none-linux-gnueabi-objdump ffserver -x | grep NEEDED commands to make sure ffserver is statically linkedmake
4. Transfer ffserver tool, ffserver.conf file (defines what media files will be served by ffserver) and media files to android with adb push command
5. Start streaming server with ./ffserver -f ffserver.conf on andoird shell
Below is a sample ffserver.conf file, which tells the ffserver to listen on rtsp port 7654. It defines two media files for streaming, /data/1.mp3 and /data/1.mp4, respectively. So make sure these files exist.
# Port on which the server is listening. You must select a different
# port from your standard HTTP web server if it is running on the same
# computer.
Port 8090
# Address on which the server is bound. Only useful if you have
# several network interfaces.
BindAddress 0.0.0.0
# Port on which the server is listening. You must select a different
# port from your standard HTTP web server if it is running on the same
# computer.
RTSPPort 7654
# Address on which the server is bound. Only useful if you have
# several network interfaces.
RTSPBindAddress 0.0.0.0
# Number of simultaneous requests that can be handled. Since FFServer
# is very fast, it is more likely that you will want to leave this high
# and use MaxBandwidth, below.
MaxClients 1000
# This the maximum amount of kbit/sec that you are prepared to
# consume when streaming to clients.
MaxBandwidth 1000
# Access log file (uses standard Apache log file format)
# '-' is the standard output.
CustomLog -
# Suppress that if you want to launch ffserver as a daemon.
NoDaemon
<Stream 1.mp4>
Format rtp
File "/data/1.mp4"
</Stream>
<Stream 1.mp3>
Format rtp
File "/data/1.mp3"
</Stream>
# port from your standard HTTP web server if it is running on the same
# computer.
Port 8090
# Address on which the server is bound. Only useful if you have
# several network interfaces.
BindAddress 0.0.0.0
# Port on which the server is listening. You must select a different
# port from your standard HTTP web server if it is running on the same
# computer.
RTSPPort 7654
# Address on which the server is bound. Only useful if you have
# several network interfaces.
RTSPBindAddress 0.0.0.0
# Number of simultaneous requests that can be handled. Since FFServer
# is very fast, it is more likely that you will want to leave this high
# and use MaxBandwidth, below.
MaxClients 1000
# This the maximum amount of kbit/sec that you are prepared to
# consume when streaming to clients.
MaxBandwidth 1000
# Access log file (uses standard Apache log file format)
# '-' is the standard output.
CustomLog -
# Suppress that if you want to launch ffserver as a daemon.
NoDaemon
<Stream 1.mp4>
Format rtp
File "/data/1.mp4"
</Stream>
<Stream 1.mp3>
Format rtp
File "/data/1.mp3"
</Stream>
To test ffserver, we can start a media player that supports media streaming, and open the url: rtsp://{ip address of the android device}:7654/1.mp3.
Labels:
android,
multimedia
Friday, May 21, 2010
invisible directshow render window
A common task we may want to achieve while creating a media application is to start media playback on a new thread, as the sample below shows:
http://code.google.com/p/rxwen-blog-stuff/source/browse/trunk/multimedia/directshow/dbg_directshow_thread_issue/dbg_directshow_thread_issue.cpp
In the menu of the sample, there are two items. "Render File" will start playback on main thread of the application. "Render New Thread" will create a new thread to playback. Everything work fine in the first case, but in the second case, the directshow rendering window isn't visible, I can only hear sound.
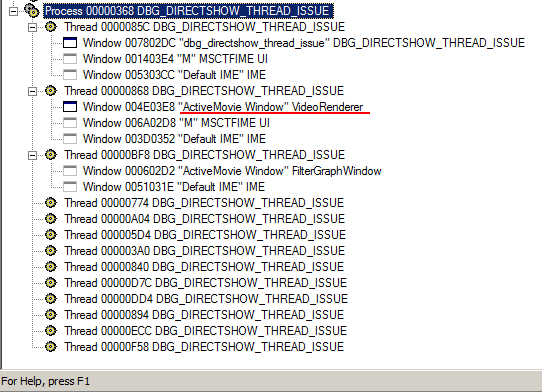
Then I debugged the application with spy++. The image below shows all windows when the media is rendered on main thread. There is a VideoRenderer window exists on main thread.
In contrast, the image below shows all windows when the media is rendered on a new thread. The VideoRenderer window doesn't exist.
I added two lines of code at the end of Render method to block the new thread so it didn't exit after the media playback started. This time, the render window can be seen. All windows are shown below, in which the VideoRenderer window is there.
Actually, the issue has to do with windows working mechanism. A window's window procedure executes on the thread that creates the window. If the corresponding thread ends, the window will also end. That's why we have to keep the new thread from exiting to keep the VideoRenderer window alive.
[quotation from programming windows by Charles Petzold]
Although Windows programs can have multiple threads of execution, each thread's message queue handles messages for only the windows whose window procedures are executed in that thread. In other words, the message loop and the window procedure do not run concurrently. When a message loop retrieves a message from its message queue and calls DispatchMessage to send the message off to the window procedure, DispatchMessage does not return until the window procedure has returned control back to Windows.
However, the window procedure could call a function that sends the window procedure another message, in which case the window procedure must finish processing the second message before the function call returns, at which time the window procedure proceeds with the original message. For example, when a window procedure calls UpdateWindow, Windows calls the window procedure with a WM_PAINT message. When the window procedure finishes processing the WM_PAINT message, the UpdateWindow call will return controls back to the window procedure.
This means that window procedures must be reentrant. In most cases, this doesn't cause problems, but you should be aware of it. For example, suppose you set a static variable in the window procedure while processing a message and then you call a Windows function. Upon return from that function, can you be assured that the variable is still the same? Not necessarily—not if the particular Windows function you call generated another message and the window procedure changes the variable while processing that second message. This is one of the reasons why certain forms of compiler optimization must be turned off when compiling Windows programs.
In many cases, the window procedure must retain information it obtains in one message and use it while processing another message. This information must be saved in variables defined as static in the window procedure, or saved in global variables.
[/quotation]
When working with directshow, it's not necessary to create a new thread explicitly. It's fine to start playback on main thread because the main thread won't be blocked.
Labels:
directshow,
multimedia
Thursday, May 20, 2010
logging with osip
As I posted before, logging is an important debugging means. In order to be truly useful and convenient, the logging module should at lease have two traits:
There is a tiny bug which prevents us using the function pointer mechanism on windows platform if we compile the osip as dynamic library. The author forgot export osip_trace_initialize_func in osipparser2.def file. So our application will end in unresolved external symbol error if we use this function. To get around this, I added the line at the very end of osipparser2.def:
To use osip logging, we need to:
An example is available here:
http://code.google.com/p/rxwen-blog-stuff/source/browse/trunk/protocol/osip_logging/osip_log.cpp
- can be turned on and off globally
- supports the concept of logging level
There is a tiny bug which prevents us using the function pointer mechanism on windows platform if we compile the osip as dynamic library. The author forgot export osip_trace_initialize_func in osipparser2.def file. So our application will end in unresolved external symbol error if we use this function. To get around this, I added the line at the very end of osipparser2.def:
osip_trace_initialize_func @416
To use osip logging, we need to:
- Compile osip with ENABLE_TRACE macro defined
- Define ENABLE_TRACE in our application
- Initialize osip logging module
- Write log message with: OSIP_TRACE (osip_trace(__FILE__, __LINE__, OSIP_INFO1, NULL, "log message"));
An example is available here:
http://code.google.com/p/rxwen-blog-stuff/source/browse/trunk/protocol/osip_logging/osip_log.cpp
Monday, May 17, 2010
sip elements lifecycle
In sip protocol, the difficult thing is the liecycle of sip elements, including dialog, transaction and message. Though defined as different layers in sip, their lifecycle usually overlaps. Message is the layer at the bottom. Transaction is the layer above message, it's comprised of a sip request message (sent by UAC) and all subsequent response messages (sent by UAS) to the request. A transaction is identified by Branch parameter in Via header. On top of the transaction layer is the dialog layer, which defines a peer-to-peer relationship between participants. Its identifier is the combination of the To tag, From tag and Call-ID.
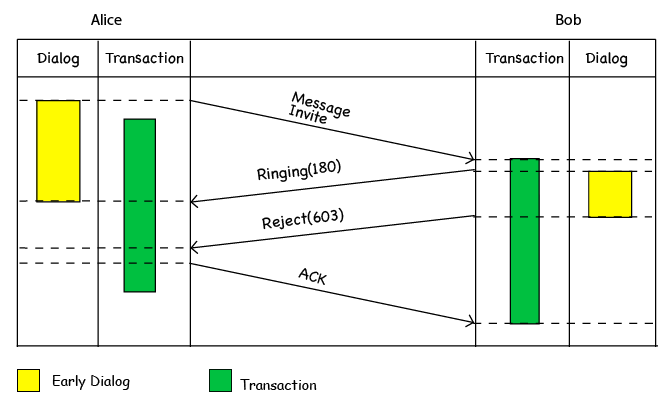
The lifecycle of elements varies depending on the actual messages exchanged. As an example, Alice called Bob, and Bob accepted the call. During the session initialization process, they exchanged a bunch of sip messages. The lifecycle of transaction and dialog elements are shown below:
(Yellow block and blue block represent the lifecyle of a dialog, indicate Early sate and Confirmed state respectively. Green block represents the lifecycle of a transaction.)
The lifecycle of elements are different if Bob rejected Alice's call. In this case, the ack message belongs to the transaction that created by the invite message, not having its own transaction anymore.
The previous example suffices to show the complexity of sip elements' lifecycle. It's import to understand the lifecycle of elements to implement a mature sip protocol stack.
The essential idea of layered design is to hide lower layer's implementation detail. In sip protocol, though it's designed as layered protocol, the lower layer isn't completely transparent.
Suppose our application runs on top of a sip protocol stack. In an ideal world, our application should only relies on the dialog layer to run. But because dialog's lifecycle doesn't fully cover the lifecycle of transactions in lower layer, our application still has to rely on transaction layer or even message layer. The dependencies on different layers of sip protocol stack make things a lot complicated.
In order to simplify things, many sip protocol stack implementations abstract another higher level layer, "call", which is not defined in sip protocol specification. The existance of this layer successfully decouples our application from those different underlying layers.
Labels:
sip
Friday, May 14, 2010
capture network traffic on windows ce
When developing network applications, it's always necessary to capture network traffic. Windows ce has built-in sniffer tool, netlog for this purpose. It captures network traffics to a file that can be examined with wireshark or network monitor.
To enable it, we need to select NDIS Packet Capturing DLL and NDIS User-mode I/O Protocol Driver in visual studio, as shown below.
Then, we can capture network traffic with following commands.
1. set capture file lacation:
4. stop capture
NetLogctl usage:
netlogctl start - start the loggging.
netlogctl load - start the loggging.
netlogctl stop - stops the loggging.
netlogctl unload - causes networking to unload the netlog component. (may destabilize system)
netlogctl pkt_size XX - sets maximum packet size captured.
netlogctl cap_size XX - sets maximum size of half capture file.
netlogctl file XXX - sets the name of the file to log.
netlogctl usb XXX - 1 => log usb , 0 => stop logging usb.
netlogctl state - print state.
netlogctl trace - print trace message state for all modules.
netlogctl trace <module> - print trace message state for specified module.
netlogctl trace <module> <filter> - set trace message state for specified module.
To enable it, we need to select NDIS Packet Capturing DLL and NDIS User-mode I/O Protocol Driver in visual studio, as shown below.
Then, we can capture network traffic with following commands.
1. set capture file lacation:
netlogctl file "\Storage Card\net"
2. start capturenetlogctl start
3. perform network activities4. stop capture
netlogctl stop
5. copy \Storage Card\net.cap[i].cap to computer and open with wireshark NetLogctl usage:
netlogctl start - start the loggging.
netlogctl load - start the loggging.
netlogctl stop - stops the loggging.
netlogctl unload - causes networking to unload the netlog component. (may destabilize system)
netlogctl pkt_size XX - sets maximum packet size captured.
netlogctl cap_size XX - sets maximum size of half capture file.
netlogctl file XXX - sets the name of the file to log.
netlogctl usb XXX - 1 => log usb , 0 => stop logging usb.
netlogctl state - print state.
netlogctl trace - print trace message state for all modules.
netlogctl trace <module> - print trace message state for specified module.
netlogctl trace <module> <filter> - set trace message state for specified module.
Subscribe to:
Posts (Atom)